Blog
August 1, 2024
Are local or global models better? Why not both?


A long-standing debate in cheminformatics is whether global property-prediction models perform better or worse than local QSAR models (see, e.g., Lascio et al., Mol. Pharmaceutics, 2023). Global models, which are trained on more data, hold the promise of learning universal patterns that underlie chemistry properties, and yet common wisdom is that local QSAR models, which are trained only on the series or program of interest, often perform better.
It’s of course hard to definitively answer the question in general, since it depends on the details of the global and local models. Our experience at Inductive is that the quality of global models can vary widely based on both the underlying training data and the way that they are trained. Nevertheless, we’ve found that usually global models that are fine-tuned on local data perform better than either global or local models alone.
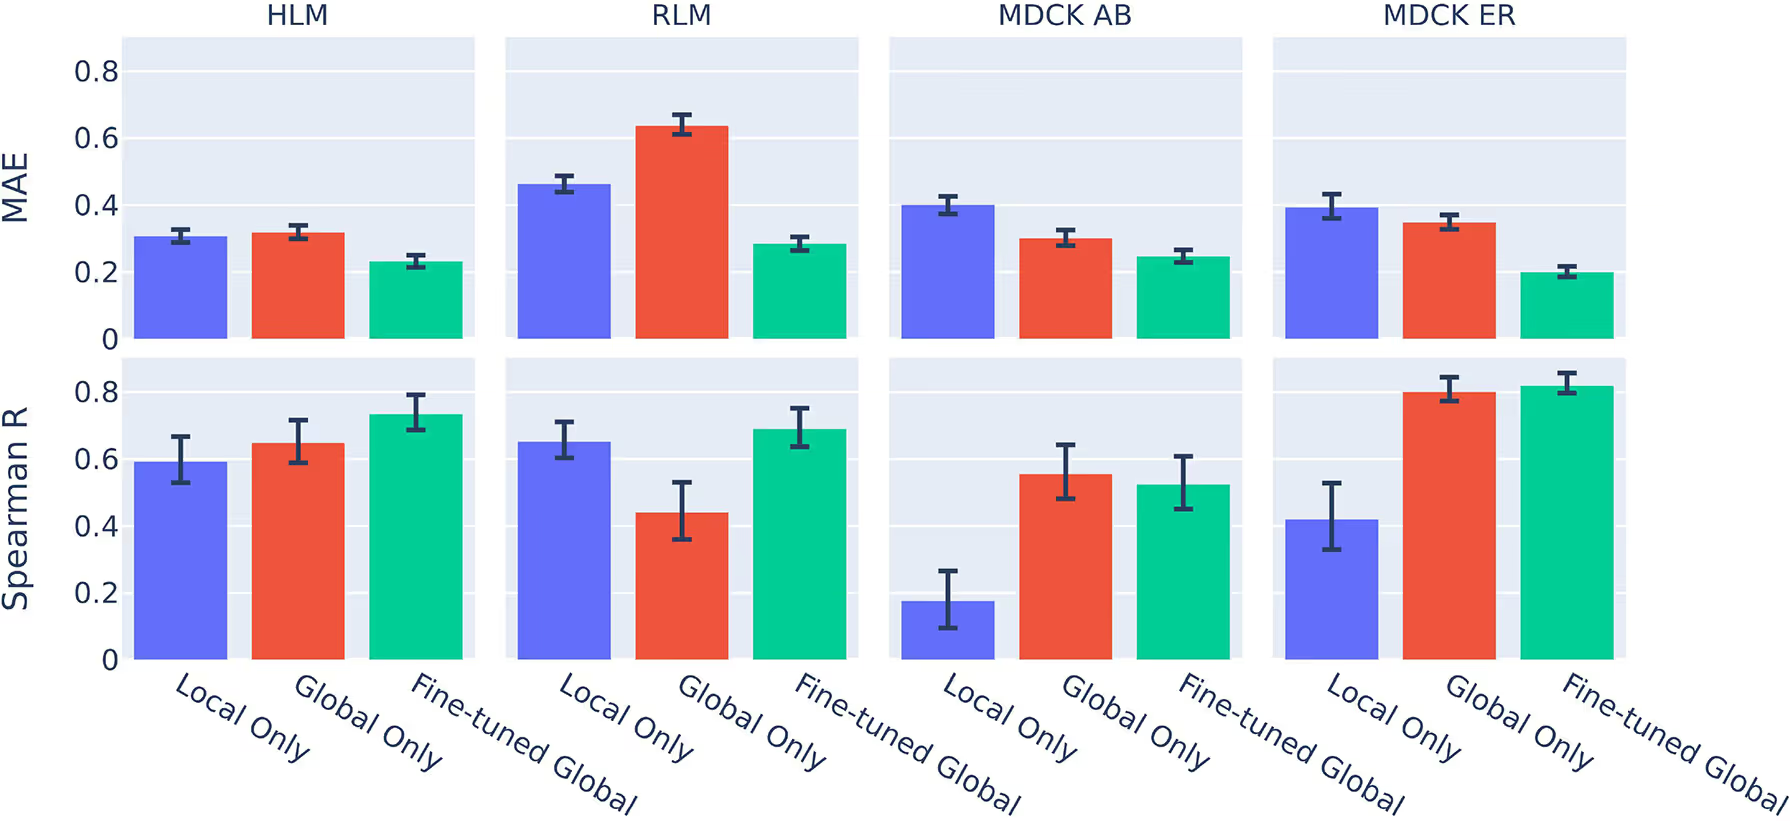
We recently had the opportunity to study this question systematically with one of our partners, Nested Therapeutics (Rich et al., ACS Med. Chem. Lett. 2024). We built models for four ADME assays: MDCK Papp (A→B), MDCK Efflux Ratio, HLM, and RLM. For each assay, we built three models: a local model trained on Nested’s program data using a third-party commercially available tool, a global-only model trained on our proprietary data set, and a global+local model that was first trained on our proprietary data set and then fine-tuned on Nested’s program data.
As shown below, the global+local modeling approach generally performed best across the assays. It achieved the lowest MAE (Mean Absolute Error) across all four properties, and the highest Spearman rank correlation across all assays except MDCK Papp (A→B), where the global model correlation was slightly higher. The impact of the global+local approach was especially pronounced for MDCK Papp (A→B), where the local-only model was not predictive at all and patterns learned from the global datasets were needed for accurate predictions.
You can read more in the full paper, where we also share other best practices we’ve seen from our work with Nested and others optimizing ADME of drug molecules, such as regular time-based and series-level evaluation (something we’ve touched on before in this blog), frequent model retraining, and ensuring models are interactive, interpretable, and integrated.
Read the full paper here.
- QC analytical reports (1H/13C/19F/2D NMR, chiral SFC)
- Propose, visualize, and triage forward and retrosyntheses
- Monitor the synthesis queue and flag stalled targets
- QC assay data as it lands and flag suspicious results
- Prioritize repeats and nominate compounds for downstream assays
- Analyze SAR and identify data gaps
- Evaluate IVIVC and suggest diagnostic experiments
- Design, enumerate, and triage analogs
- Launch and analyze physics-based workflows like docking and FEP
- Project human PK and efficacious dose
- Answer questions about a program’s history (what was learned and when)
- Track team progress against the target candidate profile
- Get new scientists up to speed on a program
- Make meeting-ready slides and figures
Prompt: I’m attaching two files with activity data, one with new data from today and one with historical data. Can you look through the new data and identify any QC issues that I should be aware of? Create a csv where every compound + assay run pair is labeled with any relevant issues.
Prompt: Do a nitrogen walk around the core of this molecule: O=C(NCC1=CC=C(C)C(F)=C1)C2=CC=C3C=C(N4[C@H](C)CCCC4)C=CN32
Prompt: Do an OH walk around this whole molecule: O=C(NCC1=CC=C(C)C(F)=C1)C2=CC=C3C=C(N4[C@H](C)CCCC4)C=CN32
Prompt: Replace the core of this molecule with this set of 5,6-ring systems (file attached): O=C(NCC1=CC=C(C)C(F)=C1)C2=CC=C3C=C(N4[C@H](C)CCCC4)C=CN32
[Related posts]
September 17, 2026
Blog
Beacon-2: Completing the reward function for chemical optimization in drug discovery
Dose is the primary reward function of pre-clinical discovery, and we believe that making it computable via Beacon-2 is a step change for AI in drug discovery. Now, instead of optimizing individual properties in isolation, agentic systems can drive the drug discovery process itself.
September 14, 2026
Blog
Meet Indy: an AI chemistry assistant designed by medicinal chemists to do medicinal chemistry
Indy, our medicinal chemistry assistant, supports drug discovery programs in improving the rigor of day-to-day analyses and decisions, by QC-ing assay data and monitoring the synthesis queue, to launching FEP, projecting human dose, and making meeting-ready SAR and synthesis slides.
June 7, 2024
Blog
Approaching AlphaFold 3 docking accuracy in 100 lines of code
AlphaFold 3 (AF3) is an exciting leap forward in our ability to predict the structure and properties of biomolecular systems. We explore how AF3 small-molecule docking compares to existing techniques and find that the story is more nuanced than headlines suggest. We conclude with thoughts on where AF3 may ultimately be most useful.
November 20, 2023
Blog
Get with the program: building ADME datasets that drive impact
Research advances often don't translate to practical impact. In ML for small molecule drug discovery, this is at least partly because benchmark datasets don't capture important components of drug programs. We show how this can happen in ADME prediction and provide a path forward for building more realistic benchmarks from existing public data.